Human Data Collection · AI Training Data

Real-World Human Data. Built for Better AI.

We collect, annotate, validate, and deliver high-quality human-generated datasets at scale to help companies train, evaluate, and improve AI models.

  • 50+Countries
  • 100+Languages & Dialects
  • HQ · Vadodara, India
Voice DataREC · hi-IN · 00:42
Image Databbox · 3 objects
Video Dataclip 04 / 06
Human Preference DataA vs B · ranked

Illustrative view · contributor density and sample tasks are not live data

100+ languages & dialects
HindiGujaratiTamilBengaliMarathiTeluguBahasaThaiVietnameseTagalogArabicFarsiTurkishGermanFrenchSpanishPolishEnglish (US)Spanish (US)French (CA)Portuguese (BR)Spanish (LATAM)SwahiliYorubaAmharicZulu
Crowd Network

Powered by a Global Contributor Network

We work with a distributed network of vetted contributors who collect real-world data — speech, images, video and text — on their own devices, in their own languages and environments. Every submission moves through automated checks and human review before it becomes part of a dataset.

  • Screened and trained per project
  • Native speakers across regions
  • Real devices, real environments
  • Centralised quality control
50K+*
Contributors

Vetted contributors in the network

50+
Countries

Clients and contributors worldwide

100+
Languages & Dialects

Indian, global and low-resource

10M+*
Data Assets

Audio, image, video and text samples

* Placeholder — replace with verified figures.

Operational flow · sample project
Illustrative — sample contributors & tasks
01Contributor
AnanyaPune
KarthikChennai
AminaNairobi
02Data Collection
Read speech · Marathi
42/60 clips70%
Street signage photos
18/25 images72%
Chat prompts · Tamil
31/40 turns78%
03Quality Check
Auto checksclip_0428.wav
  • Audio level & noise
  • Duration within spec
  • Script match
  • Duplicate scan
Check score3 / 4 passed
04Validation
RVReviewer 1Transcript matches
MKReviewer 2Speaker & quality OK
Verified sample2 of 2 reviewers agree
05AI Dataset
mr-IN_read_speechBatch 14 · ready
  • audio/ · .wav
  • transcripts/ · .json
  • metadata.csv
  • qc_report.pdf
ConsentedQC passedDe-identified
Data Types

Data That Teaches AI How the Real World Works

Every dataset starts with people recording, photographing, writing and judging in real conditions. These are the data types we collect, annotate and validate.

Visuals are illustrative samples

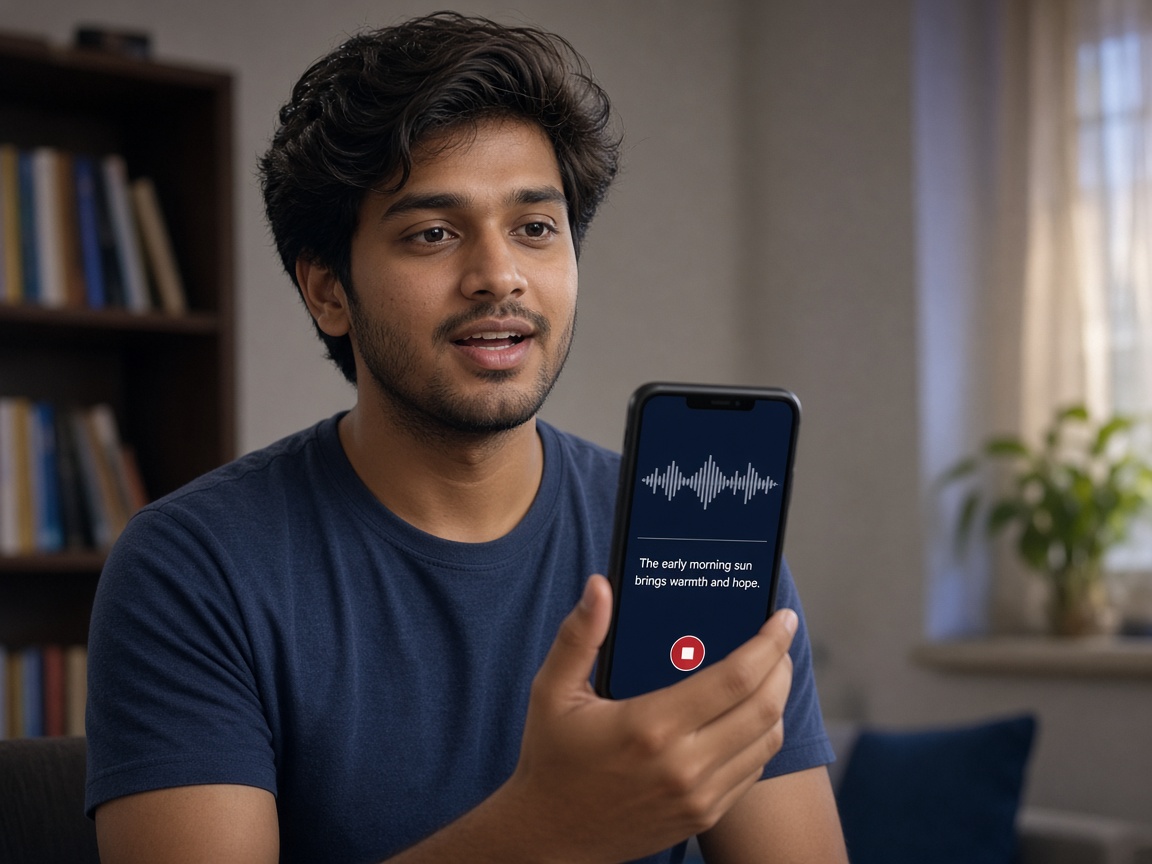
Voice & Speech

01

Native-language speech collected from diverse speakers for speech recognition, conversational AI, and voice assistants.

Real-world example
Read prompts and spontaneous conversation in Hindi, Gujarati, Tamil and other languages, recorded in homes, streets and vehicles.
Collection method
Scripted and guided recording on contributors' phones; studio sessions where acoustic control matters.
AI use case
Speech recognition (ASR), text-to-speech voices, wake words and voice assistants.
Images

02

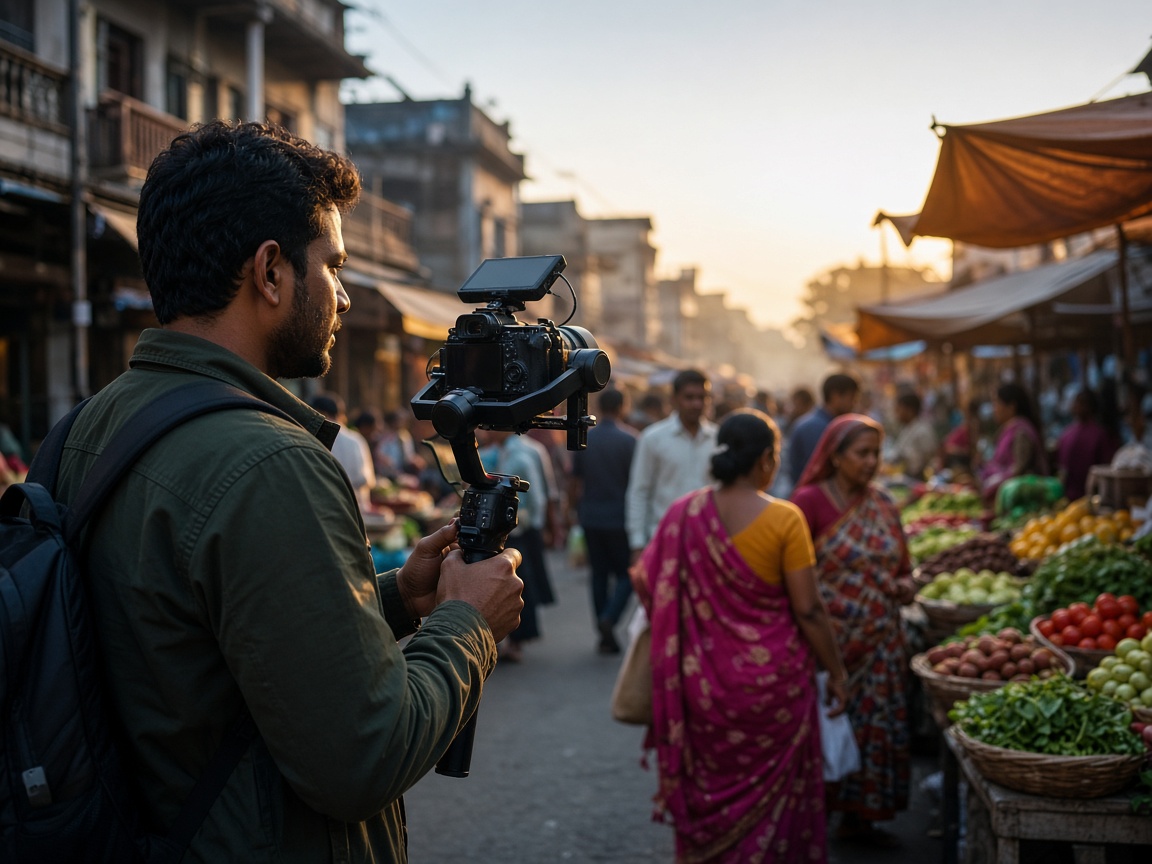
Photos of real objects, places and scenes, captured in varied lighting, angles and environments, then labelled.

Real-world example
Street scenes, retail shelves, household items and food photographed across different cities.
Collection method
Guided capture tasks with framing and quality checklists, followed by box, polygon or class labels.
AI use case
Object detection, visual search and product recognition.

Video

03

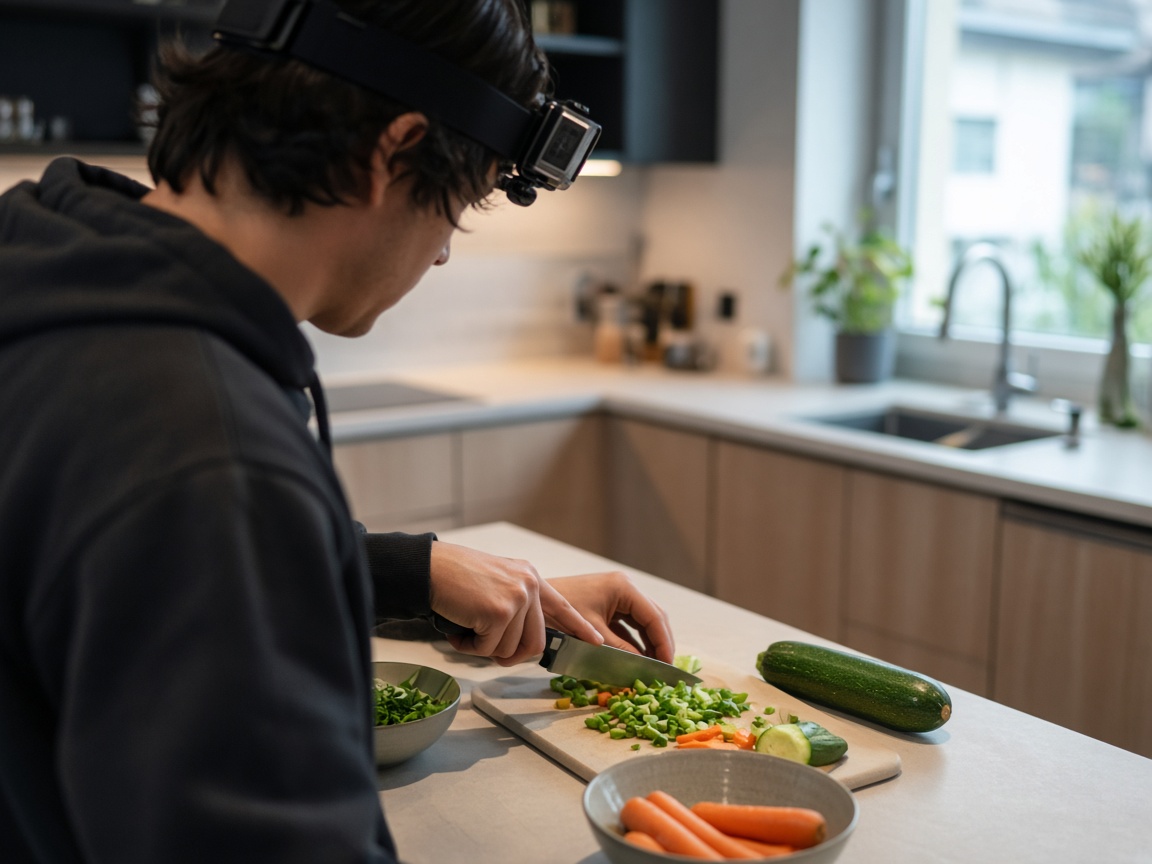
Short clips of everyday activities and interactions, recorded to a script and segmented by action.

Real-world example
First-person clips of cooking, shopping or commuting; gesture and hand-object interaction recordings.
Collection method
Phone or head-mounted camera recordings with timestamped action segments added in review.
AI use case
Action recognition, video understanding and embodied AI.

Text

04

Human-written and human-annotated text that reflects how people actually type, ask and talk.

Real-world example
Natural user queries, chat dialogues, reviews and code-mixed or transliterated Indic text.
Collection method
Prompted writing and paraphrasing by native speakers, plus intent and entity annotation.
AI use case
LLM fine-tuning, intent classification, entity extraction and translation.

Human Preference

05

Side-by-side judgements of model outputs by trained reviewers, each with a written reason.

Real-world example
Choosing the better of two chatbot answers for accuracy, helpfulness and safety.
Collection method
Pairwise ranking and rubric scoring, with overlapping reviewers to measure agreement.
AI use case
RLHF reward models, model evaluation and red-teaming.

Geospatial Data

06

Location-tagged observations collected on the ground by contributors who are physically there.

Real-world example
Storefront and signage photos, points of interest and road conditions, each with GPS coordinates.
Collection method
Field tasks with GPS check-in, route walks and geo-tagged photo capture.
AI use case
Map and POI enrichment, local search, delivery and mobility models.

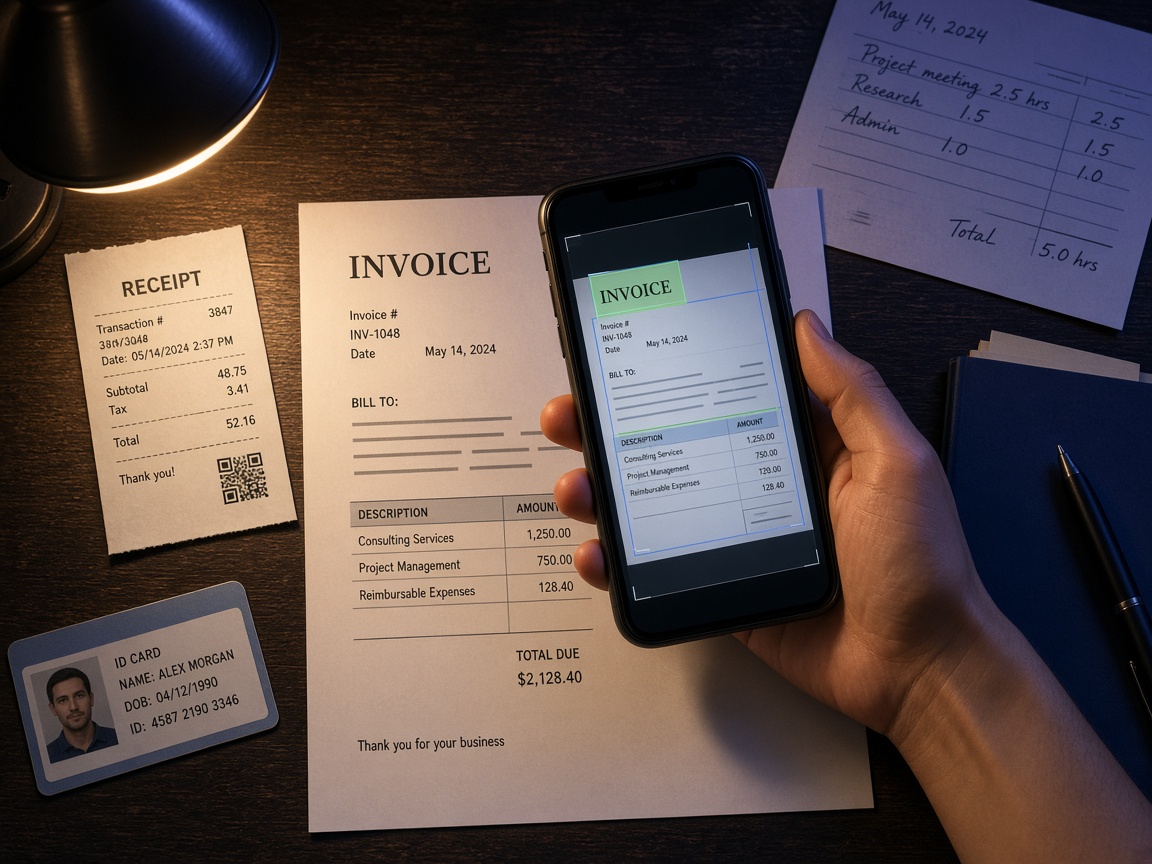
OCR & Document Data

07

Real-world documents and handwriting, captured under varied conditions and transcribed field by field.

Real-world example
Receipts, invoices, printed forms and handwritten notes in Latin and Indic scripts.
Collection method
Phone capture at different angles and lighting, then box-level transcription and key-value tagging.
AI use case
OCR, document understanding and form or invoice extraction.

Multimodal Data

08

Paired data where speech, images, video and text describe the same moment and are aligned in time.

Real-world example
A cooking video with narration, transcript and action labels; a photo with a spoken description.
Collection method
Paired capture tasks with time-synced annotation across each modality.
AI use case
Vision-language models, multimodal assistants and video Q&A.
Crowd Collection Workflow

Distributed Collection. Centralized Quality Control.

Contributors in many cities work at the same time on their own devices. Every submission then passes the same review and validation gates, so the dataset you receive is consistent no matter who recorded it.

Collection pipelineIllustrative
AKRMSNFBPJLOMTQC GATEFormat & metadataAudio / image qualityGuideline matchDuplicates2nd-pass samplingreturned for reworkDATASETDISTRIBUTED CONTRIBUTORSCENTRALIZED QCSINGLE OUTPUT

Many contributors→One QC gate→One dataset

01

Recruit

Source and screen contributors by language, region, device and the demographic mix the project needs.

Screened profiles
02

Assign Tasks

Route tasks with clear instructions, examples and quotas so coverage stays balanced across people and places.

Briefs + quotas
03

Collect

Contributors record, photograph, write or label on their own devices, in real environments, in parallel.

Distributed
04

Review

Automated checks for format, duration, noise and duplicates, then reviewers check each item against the guidelines.

Auto + human
05

Validate

An independent second pass on samples and flagged items, with agreement checks and rework where needed.

Centralized QC
06

Deliver

Clean, consistently formatted data with metadata and documentation, delivered in your schema.

One dataset
Real-World Collection

From Human Experience to AI Training Data

What collection looks like in practice: people completing structured tasks on their own phones and laptops, with every submission tracked, checked and traceable.

Sample tasks · illustrative contributors
Contributor reading a prompt aloud into a smartphone
REC 00:07
Prompt 12 / 40

“Remind me to call the bank tomorrow at ten.”

Hindi · read speechNoise: low ✓
Speech · Read promptsRecording

Recording voice samples on a smartphone

Contributors read short prompts in their own language and accent, at home or outdoors. The app checks length and background noise before upload.

RM

Rahul · Indore

Sample contributor

Prompt 12 of 40
Contributor photographing an invoice with a phone
Document capture · 3 of 5
AUTO · 12 MP
Capture checklist
  • All four corners visible
  • No glare or shadow
  • Text sharp and legible
  • Hold steady
Image · Guided captureUploaded

Photographing documents, products and roads

A capture checklist guides framing, lighting and focus, so receipts, shelves and street scenes arrive usable the first time.

MN

Meera · Kochi

Sample contributor

Photo 3 of 5
First-person video recording of a contributor chopping vegetables
REC 00:00:24
1080p · 30 fps
Clip 2 / 6 · Kitchen activity00:24 / 00:45
Video · First-personIn review

Recording short videos of everyday activities

Short phone or head-mounted clips of real tasks such as cooking, with action segments marked during review.

FB

Farhan · Lucknow

Sample contributor

Clip 2 of 6
Multi-turn dialogueTurn 3 / 6
I need to reach Ahmedabad by tomorrow noon. Which trains work?
Two overnight trains arrive before 11 am. Do you prefer sleeper or AC?
Your turn · write the next user message

Sleeper is fine, is there one under Rs 600?

Natural phrasingStays on topicNo personal data
Text · Dialogue writingSubmitted

Completing conversational AI tasks

Native speakers write natural multi-turn conversations, following a scenario and simple quality rules shown in the task.

AK

Ananya · Pune

Sample contributor

Turn 3 of 6
Prompt

How do I reset my UPI PIN if I forgot it?

Response A
Response B PREFERRED
Accuracy
Clarity
Safety
Preference · PairwiseValidated

Comparing two AI responses

Trained reviewers choose the better answer, score it on a rubric and explain why, giving reward models a clear signal.

DO

Daniel · Nairobi

Sample contributor

Pair 18 of 50
Street market scene being labelled with bounding boxes
person
camera
produce
person
IMG 14 / 20 · 4 objects
Annotation · Bounding boxesLabeling

Labeling images

Annotators draw boxes and assign classes in a browser tool; a second reviewer checks a sample of every batch.

PJ

Priya · Jaipur

Sample contributor

Image 14 of 20
AI Training Data Categories

Built for Every Stage of the AI Data Pipeline

From the first recording on a contributor's phone to the feedback that fine-tunes a model, every stage is run by trained people and checked before it moves on.

  1. 01
    Collect→ Raw samples

    Data Collection

    Speech, image, video and text captured by real contributors in real settings.

    Human Preference Data

    People compare, rank and rate outputs to capture what humans actually prefer.

  2. 02
  3. 03
  4. 04
    Curate→ Balanced set

    Data Curation

    Balanced by language, region, demographic and condition; duplicates removed.

  5. 05
  6. 06
    Train AI→ Model feedback

    RLHF / Human Feedback

    Human feedback loops that align model behaviour after training.

    AI Response Evaluation

    Raters score accuracy, safety and helpfulness of model responses.

Quality Control

Quality Is Built Into Every Dataset

Quality isn't a final inspection. It is checked at seven points, from who we let in to what we ship, so large datasets stay consistent and reliable.

  1. 01

    Contributor Screening

    Language, device and skill tests before anyone joins a project.

  2. 02

    Task Instructions

    Clear guidelines, examples and edge cases for every task type.

  3. 03

    Automated Checks

    Format, duration, noise, blur and duplicate checks on upload.

  4. 04

    Human Review

    Trained reviewers inspect each sample against the spec.

  5. 05

    Multi-Level Validation

    Second-pass and expert validation on a sampled share of work.

  6. 06

    Quality Scoring

    Per-sample and per-contributor scores drive rework and routing.

  7. 07

    Final Dataset

    Only verified samples ship, with metadata and documentation.

Rework loop

A sample that fails any gate goes back to its contributor with specific feedback, and contributor scores decide who gets which tasks next.

QC panel · sample

Batch HI-SPCH-0417 · Hindi conversational speech

Illustrative figures
98.7%
Quality Score
94.2%
Annotator Agreement
99.1%
Spec Compliance

Pass rate by check

  • Format & metadata99.6%
  • Audio clarity / SNR97.8%
  • Transcript accuracy96.9%
  • Consent & identity100.0%
  • Duplicate detection99.2%

Sample validation log

SampleLanguageContributorScoreStatus
HI-0417-0192VoiceHindiAnanya · Pune99.2 Verified
GU-0417-0088VoiceGujaratiRavi · Surat98.6 Verified
TA-0417-0231TranscriptTamilMeena · Chennai97.4 Verified
BN-0417-0143VoiceBengaliArjun · Kolkata91.8 In review
MR-0417-0310TranscriptMarathiSneha · Nagpur84.5 Rework

Sample values — replace with live data.

Enterprise Use Cases

Helping AI Teams Build Better Models

Whatever your model does, it learns from data people created. We collect and prepare that data for the teams building these systems.

Generative AI

Instruction, dialogue and preference data that teaches models to follow people, not just patterns.

Data that feeds it

Prompt–response pairsPreference rankingsMultilingual textImage–caption pairs

Computer Vision

Real-world images and video across devices, lighting and environments, annotated to your schema.

Data that feeds it

PhotosVideo clipsBounding boxesSegmentation masks

Speech AI

Native speakers, accents and acoustic conditions for ASR and TTS.

Data that feeds it

Speech audioTranscriptsStudio TTS

Autonomous Systems

Road, street and outdoor scenes captured where the systems will operate.

Data that feeds it

Road videoGeo-tagged imagesObject labels

Robotics

First-person footage of people handling everyday objects and tasks.

Data that feeds it

Egocentric videoAction labelsKeypoints

Search & Recommendation

Human relevance judgements that reflect what users actually want.

Data that feeds it

Relevance ratingsQuery logsProduct images

Conversational AI

Natural, multi-turn conversations in the languages your users speak.

Data that feeds it

Dialogue audioChat transcriptsIntent labels

Document Intelligence

Forms, receipts and handwriting from real documents, keyed and verified.

Data that feeds it

Document scansOCR textField labels

AI Safety & Evaluation

Trained raters probe and score model outputs for harm, bias and accuracy.

Data that feeds it

Response ratingsRed-team promptsRubric scores

Multilingual AI

Indian, global and low-resource languages from native contributors.

Data that feeds it

SpeechParallel textDialect audio
Geographic Scale

Data Collection Across Regions and Languages

Contributors in every major market collect speech, images, video and text in their own languages and environments — coordinated from our head office in Vadodara, India.

Illustrative figures · editable
Collection activity
Selected region

India

20K+*
Contributors
Relative activity100 / 100
Languages
HindiGujaratiTamilBengaliMarathiTelugu
Sample tasks In progress
  • Read speech · Hindi56%
  • Conversational turns · Gujarati53%
  • Street & storefront photos · India23%

* Placeholder — replace with verified figures. Activity levels and sample tasks are illustrative, not live data.

Data Operations

Data Operations You Can See Running

Every project runs through one operations console: contributors, tasks, review queues, quality and coverage, tracked day by day.

Operations console · OverviewIllustrative — sample values

Active Contributors

12,480

+6.2% vs prev.

Tasks Completed

1.84M

+11.4% vs prev.

Datasets Collected

326

+18 vs prev.

Languages Covered

100+

Coverage

Countries Covered

50+

Coverage

Quality Score

98.7%

+0.4 vs prev.

Tasks Under Review

8,912

−3.1% vs prev.

Validated Samples

1.21M

+9.8% vs prev.

Tasks completed per day

Thousands
137Ktasks on day 14
0K50K100K150K
D1D7D14

Tasks by modality

Share
  • Voice & Speech34%
  • Image22%
  • Video16%
  • Text & Preference18%
  • Documents10%

Contributor activity

Sample feed
  • AN

    Ananya · Pune submitted 40 voice clips

    Hindi2m ago

  • KO

    Kofi · Accra photographed 25 retail shelves

    Image4m ago

  • LU

    Lucía · Bogotá ranked 60 response pairs

    Preference6m ago

  • IM

    Imran · Dubai recorded 12 egocentric clips

    Video9m ago

  • PR

    Priya · Vadodara transcribed 18 audio files

    Gujarati11m ago

Task completion

Active projects
  • Conversational speech · 6 Indic languages78%
  • Retail shelf images · 4 regions54%
  • Egocentric kitchen video31%
  • RLHF preference pairs92%

Review queue

  • Automated checks42%
  • Human review35%
  • Expert validation23%

Geographic distribution

Contributors
  • India20K+
  • Southeast Asia8K+
  • Europe6K+
  • North America5K+
  • Middle East5K+
  • Latin America3K+
  • Africa3K+

Illustrative dashboard — sample values, not live data. Contributor names are sample identities.

Why Dhvani.ai

Why Companies Work With Us

01

Scale

Access distributed human contributors across markets and demographics.

ANRVMKLSKOIMAcross markets
02

Speed

Launch and scale data collection projects quickly.

BriefPilotScale
03

Diversity

Collect data across languages, regions, environments, and user profiles.

हिन्दीગુજરાતીதமிழ்العربيةKiswahiliEspañol
04

Quality

Multi-stage validation and quality control.

Auto L1 L2 Expert
05

Customization

Design collection workflows around your exact AI training requirements.

LanguageGujarati
SettingOutdoor
DeviceAndroid
06

Security

Enterprise-grade processes for sensitive data collection and handling.

ISO 9001:2015-aligned GDPR-aligned HIPAA-aligned
FAQ

Questions AI teams ask us

How we collect, validate and deliver human-generated training data.

Still have questions?

Talk to our team directly — we usually reply within a few hours.

Dhvani.ai is a global AI data collection and AI solutions company. We collect, process, annotate, validate and evaluate multilingual, multimodal data for NLP, LLM, speech and computer vision — and we build AI agents, chatbots and automation on top of it.

Start a Project

Need Real-World Data for Your Next AI Model?

Tell us what your AI model needs. We'll design the collection, annotation, validation, and delivery workflow around your requirements.

Your data brief

4 questions
  • Modality

    Speech, image, video, text…

  • Languages & regions

    Who and where to collect from

  • Annotation & QA

    Schema, guidelines, review levels

  • Volume & timeline

    Pilot first, then scale

Share what you know. We'll help shape the rest.