Document Collection
Consent-based collection of real and synthetic-safe documents across formats, scripts, devices and capture conditions.
Turn complex documents into AI-ready training data.
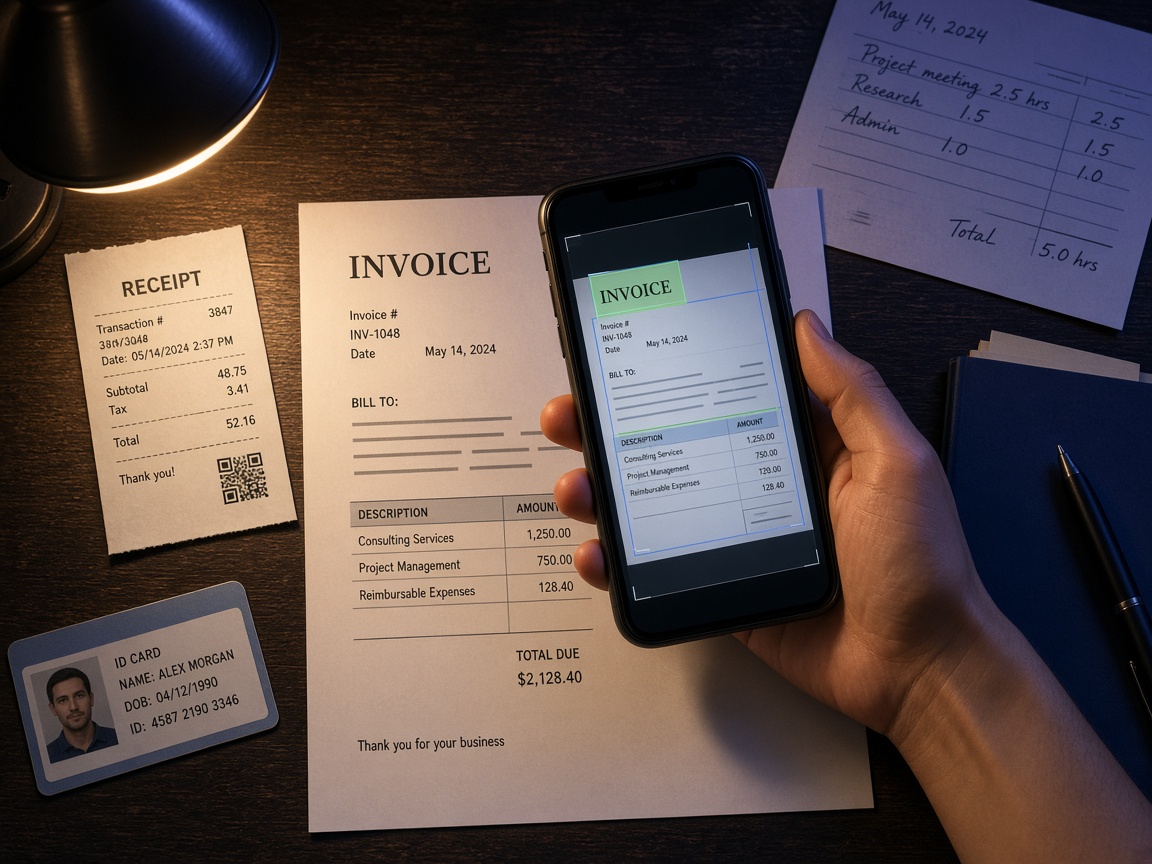
Turn complex documents into AI-ready training data.
Dhvani.ai collects, transcribes and annotates real-world documents to train OCR, Document AI and Intelligent Document Processing systems. Our multilingual teams handle Indian and global scripts, messy handwriting, low-quality scans and complex layouts — so your models perform on the documents your customers actually upload.
Consent-based collection of real and synthetic-safe documents across formats, scripts, devices and capture conditions.
Line, word and character-level transcription of printed and handwritten text by native-script annotators.
Bounding boxes, key-value pairs, tables and reading order labeled for structured extraction models.
Labeling documents by type, language and quality to train routing and classification models.
“Dhvani.ai turns real-world paperwork into structured, AI-ready training data.”
We capture your use case, data specification, languages, volumes, timelines and compliance needs.
We design the workflow, write guidelines and deliver a pilot batch for your sign-off.
Dedicated teams scale delivery with daily progress tracking and a single point of contact.
Multi-layer QA, sampling and reporting against agreed metrics on every delivery.
Secure delivery in your format, plus revisions, iterations and long-term support.
Quick answers to common questions about this service.
Still have questions?
Talk to our team directly — we usually reply within a few hours.
Yes. Our native-script teams transcribe and annotate printed and handwritten documents in Indian and international languages.
Share your languages, volumes and timelines — we’ll respond with a scoped plan within one business day.