TTS & Speech Dataset Recording
Studio-grade recordings for neural TTS, ASR training, and speech synthesis models.
Voice & Speech Solutions
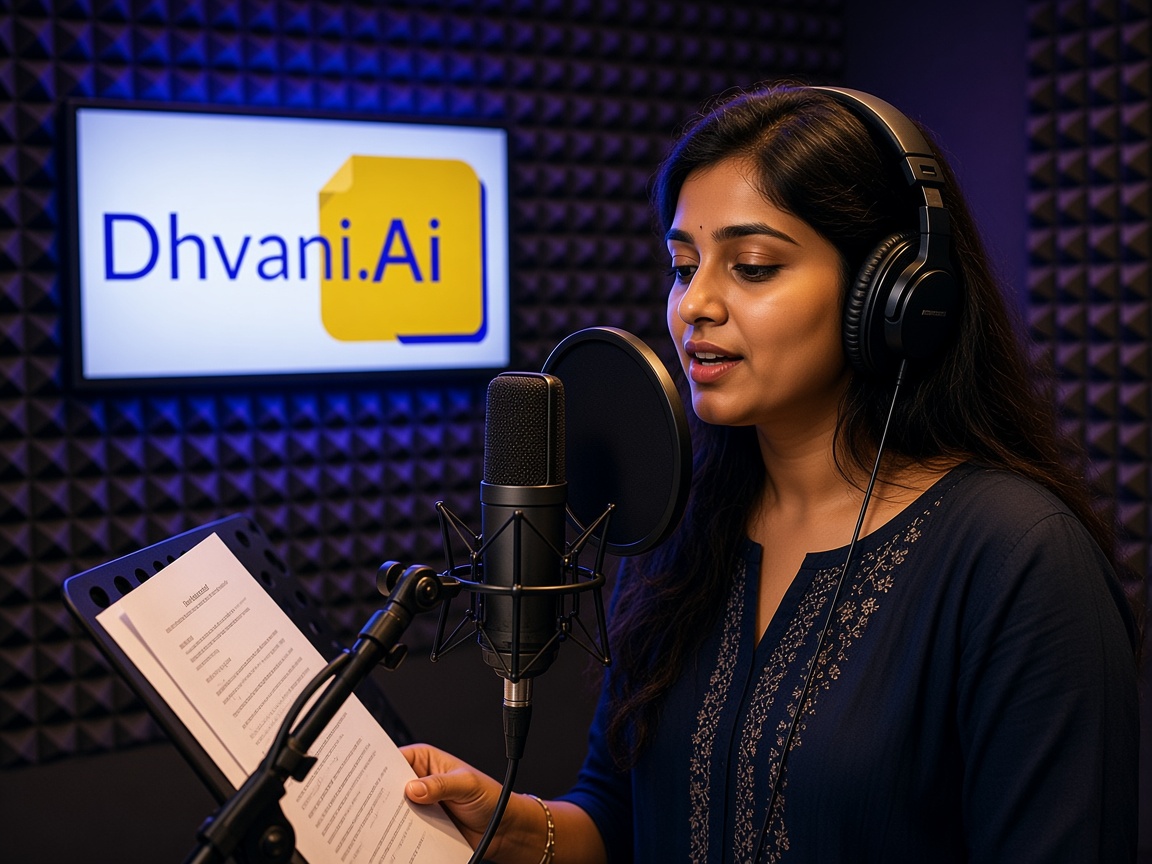
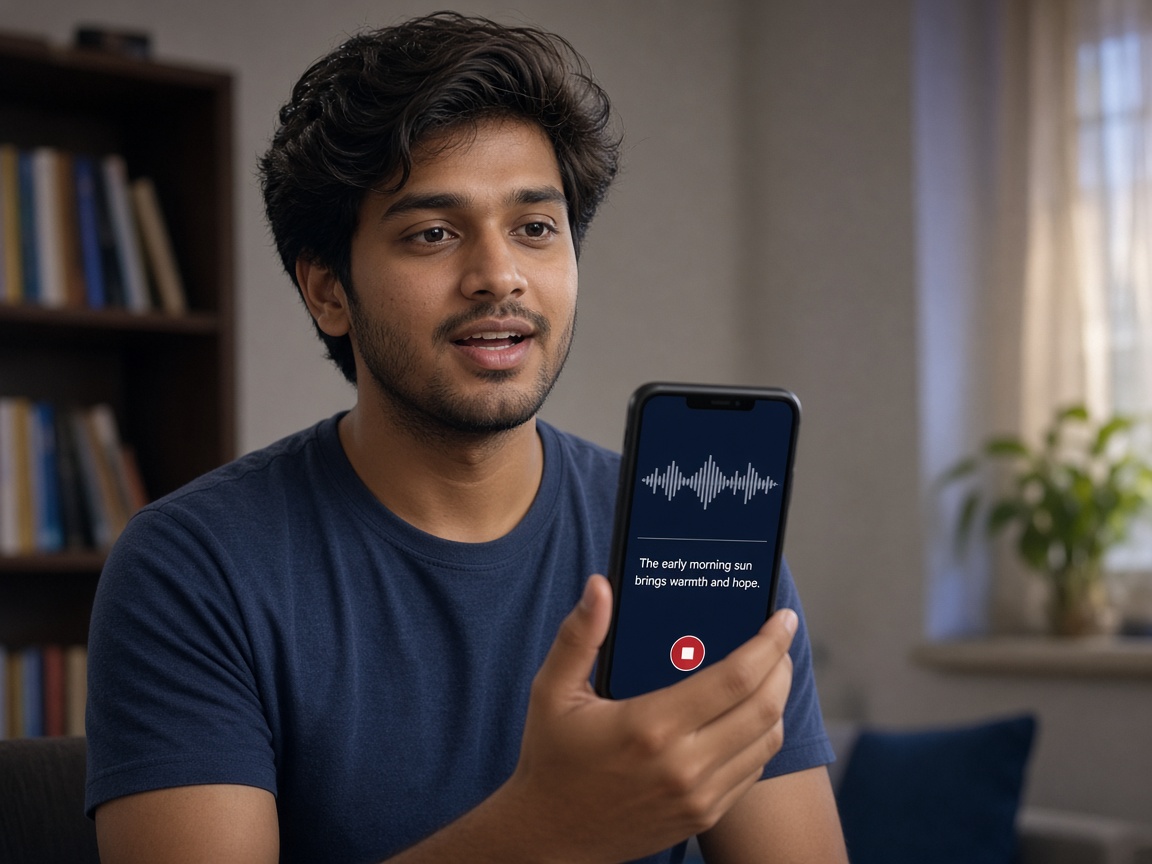
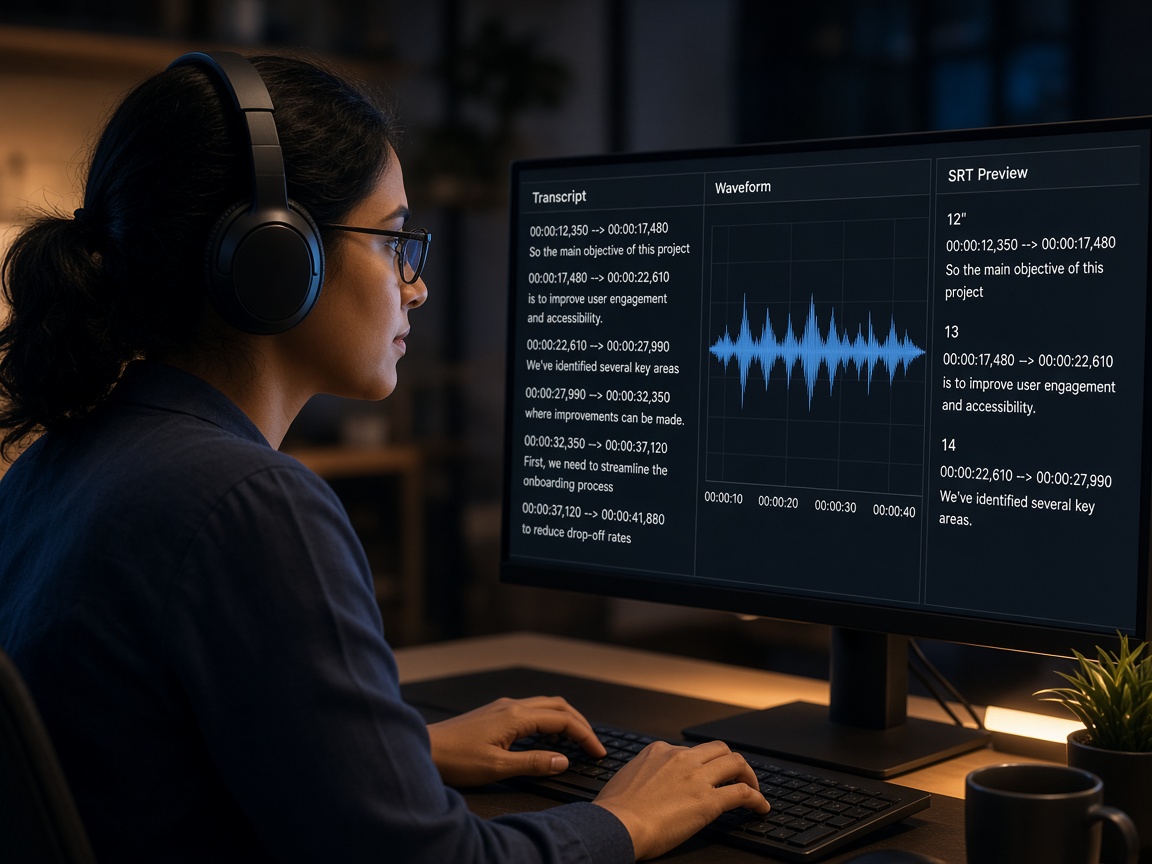
Dhvani.ai provides professional studio recording services delivering high-fidelity Text-to-Speech (TTS) and speech datasets for advanced AI and ML speech applications.
With access to acoustically controlled studios, professional equipment, and native voice talent worldwide, we create production-ready audio that meets enterprise and research-grade standards.
Studio-grade recordings for neural TTS, ASR training, and speech synthesis models.
Multilingual dubbing, scripted prompts, and conversational recordings for voice assistants and generative speech models.
Clean, consistent audio optimized for AI training, fine-tuning, and evaluation.
“Dhvani.ai delivers studio-quality speech data—clear, natural, and built for next-generation AI voice systems.”
We capture your use case, data specification, languages, volumes, timelines and compliance needs.
We design the workflow, write guidelines and deliver a pilot batch for your sign-off.
Dedicated teams scale delivery with daily progress tracking and a single point of contact.
Multi-layer QA, sampling and reporting against agreed metrics on every delivery.
Secure delivery in your format, plus revisions, iterations and long-term support.
Quick answers to common questions about this service.
Still have questions?
Talk to our team directly — we usually reply within a few hours.
Yes. We cast native voice talent, prepare phonetically balanced scripts and record in controlled studios to build TTS voices in Indian and international languages.
Share your languages, volumes and timelines — we’ll respond with a scoped plan within one business day.