Human-Made Transcription
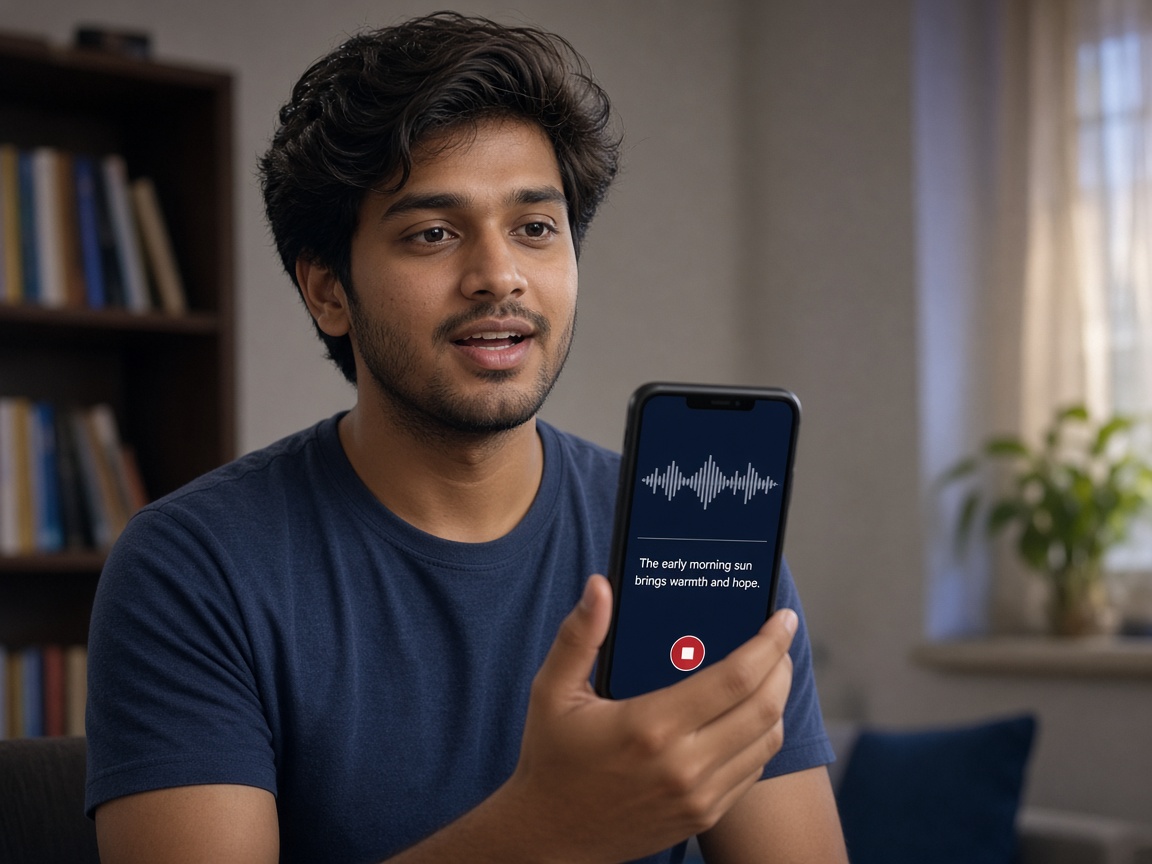
High-accuracy verbatim and clean-read transcription for speech, audio, and video data.
100% Human-Made Transcription Services
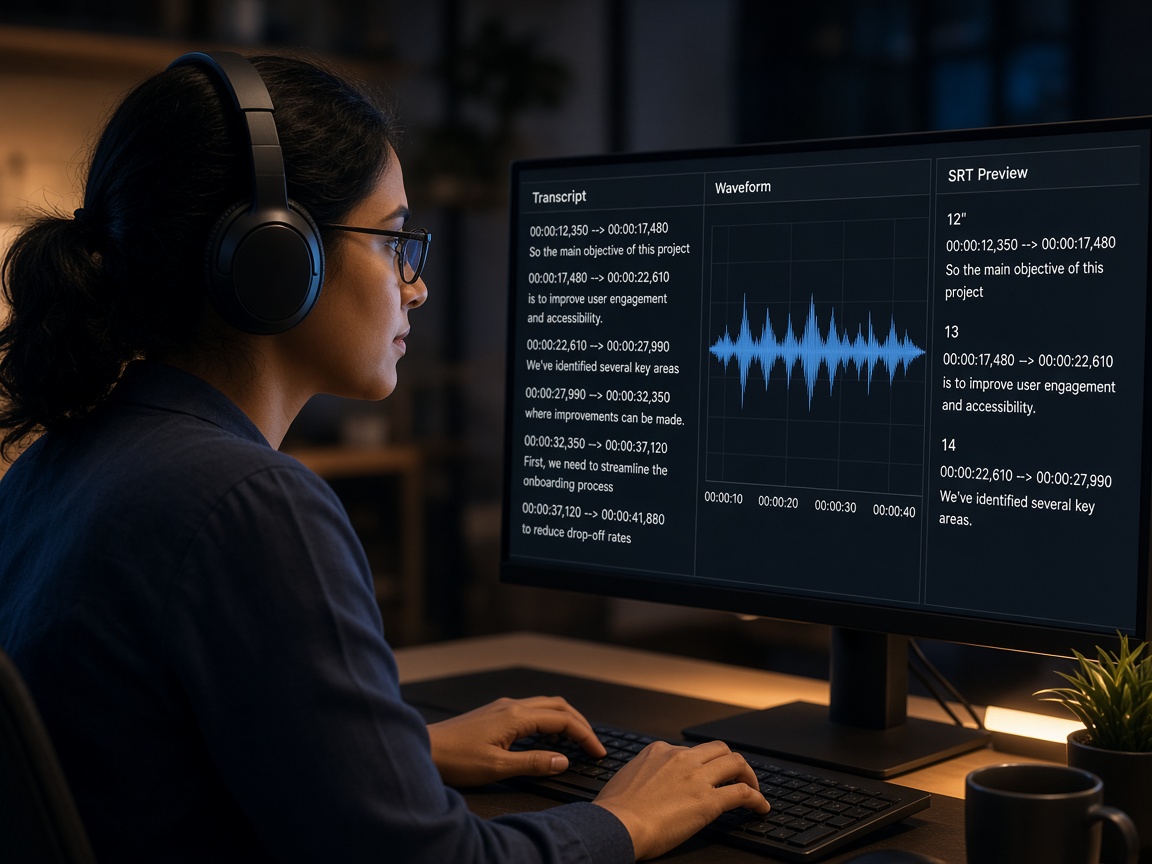
Dhvani.ai provides end-to-end language data services with a strong focus on accuracy, consistency, and global linguistic coverage. All transcription work is 100% human-made, ensuring natural language understanding, cultural accuracy, and enterprise-grade quality.
We support 100+ GlobalX languages, delivering scalable transcription and language services for AI training, compliance, and content localization.
High-accuracy verbatim and clean-read transcription for speech, audio, and video data.
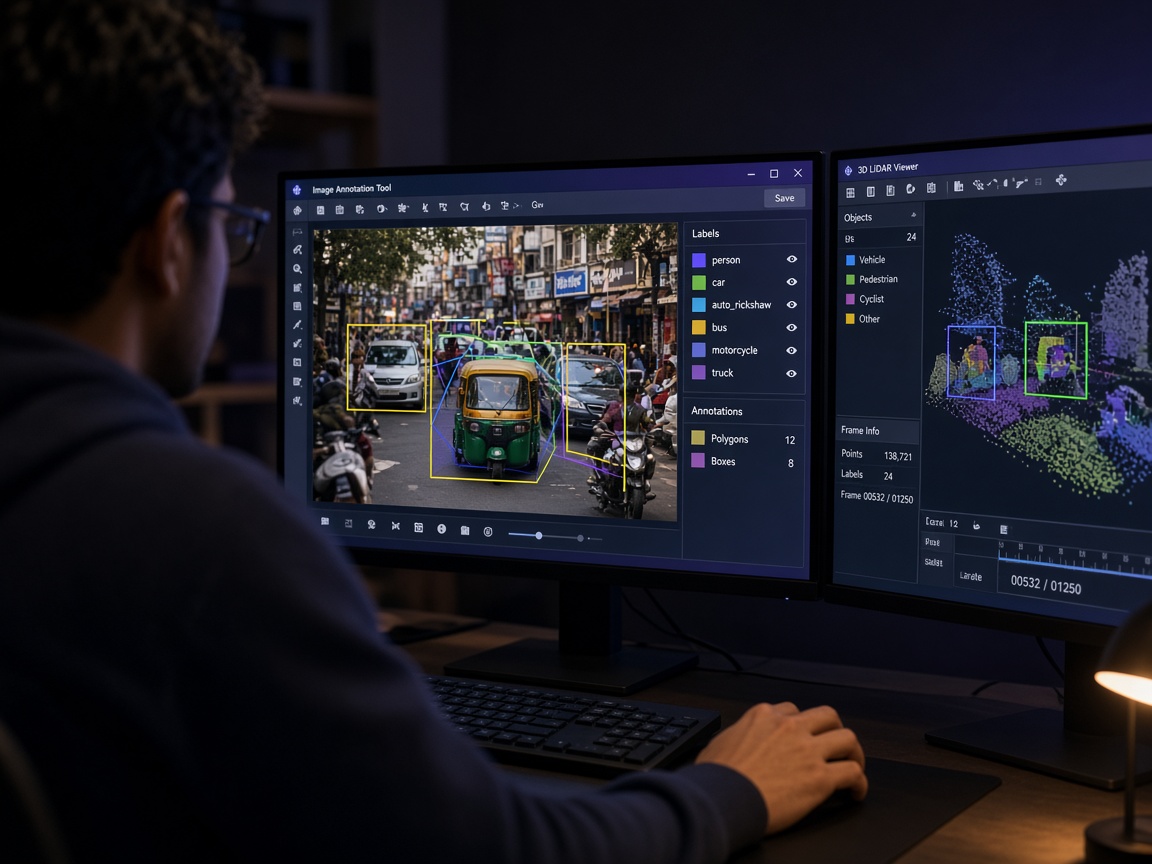
Sentence-level and time-stamped segmentation optimized for ASR, NLP, and LLM training pipelines.
Linguistic review to ensure grammatical accuracy, consistency, and adherence to client style guides.
Multilingual translation with native-language experts, maintaining semantic meaning and cultural relevance.
Verified multilingual QA with multi-stage review processes to meet enterprise and research-grade standards.
“Dhvani.ai delivers reliable, multilingual language data—built for accuracy, scale, and AI readiness.”
We capture your use case, data specification, languages, volumes, timelines and compliance needs.
We design the workflow, write guidelines and deliver a pilot batch for your sign-off.
Dedicated teams scale delivery with daily progress tracking and a single point of contact.
Multi-layer QA, sampling and reporting against agreed metrics on every delivery.
Secure delivery in your format, plus revisions, iterations and long-term support.
Quick answers to common questions about this service.
Still have questions?
Talk to our team directly — we usually reply within a few hours.
All transcription work is 100% human-made by trained, native-language transcribers. Tools may assist with workflow, but every transcript is produced and reviewed by people.
Share your languages, volumes and timelines — we’ll respond with a scoped plan within one business day.