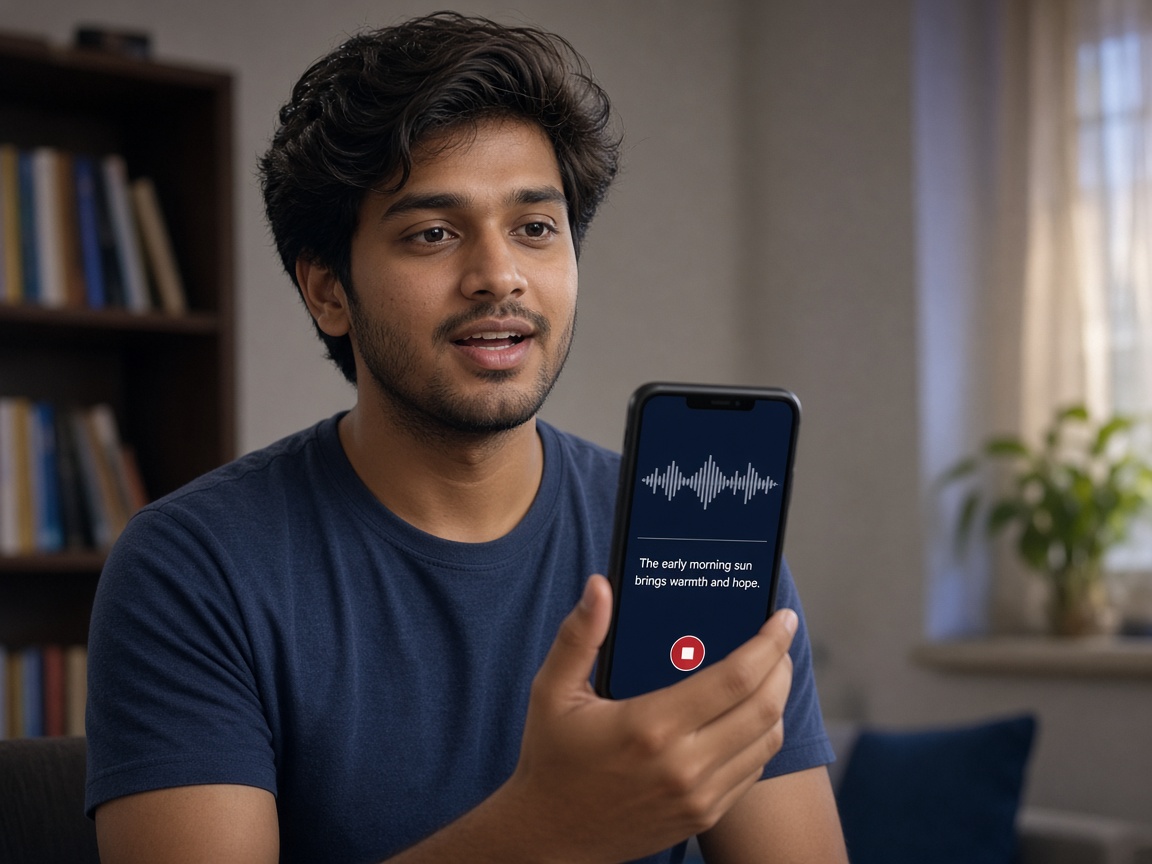
Mobile App-Based Collection
Secure voice data collection via Android & iOS applications, enabling scalable crowd-based and controlled speech recording across diverse demographics and accents.
Speech Datasets for Natural Language Processing
Dhvani.ai delivers end-to-end Speech Dataset Collection services designed for training and evaluating modern Speech AI, ASR, TTS, and Conversational AI systems. We enable large-scale, high-quality voice data collection through multiple secure recording channels, ensuring flexibility, scalability, and global reach.
From wake-word and command datasets to hundreds of hours of spontaneous conversational speech, every programme is designed around your model’s real users — their languages, accents, age groups, devices and acoustic environments. Scripts, prompts, speaker demographics and recording specifications are agreed upfront, so the data you receive is balanced, consistent and ready to train on.
Secure voice data collection via Android & iOS applications, enabling scalable crowd-based and controlled speech recording across diverse demographics and accents.
Browser-based speech collection for fast onboarding, remote participation, and enterprise-controlled recording workflows without device limitations.
Professional, studio-grade speech recording in controlled acoustic environments, ideal for TTS, AI dubbing, voice cloning, audiobooks, and high-fidelity speech datasets.
“Dhvani.ai ensures accurate, diverse, and production-ready speech datasets—at global scale.”
We capture your use case, data specification, languages, volumes, timelines and compliance needs.
We design the workflow, write guidelines and deliver a pilot batch for your sign-off.
Dedicated teams scale delivery with daily progress tracking and a single point of contact.
Multi-layer QA, sampling and reporting against agreed metrics on every delivery.
Secure delivery in your format, plus revisions, iterations and long-term support.
Quick answers to common questions about this service.
Still have questions?
Talk to our team directly — we usually reply within a few hours.
We collect through our Android & iOS mobile app, a browser-based web app, and professional acoustic studios. The channel is chosen based on the audio quality, scale and speaker diversity your model needs.
Share your languages, volumes and timelines — we’ll respond with a scoped plan within one business day.