OCR & Document AI: Preparing Training Data for Real-World Documents
Invoices, receipts, ID cards and handwritten forms are messy. Here is how to build OCR and Document AI training data that holds up in production.
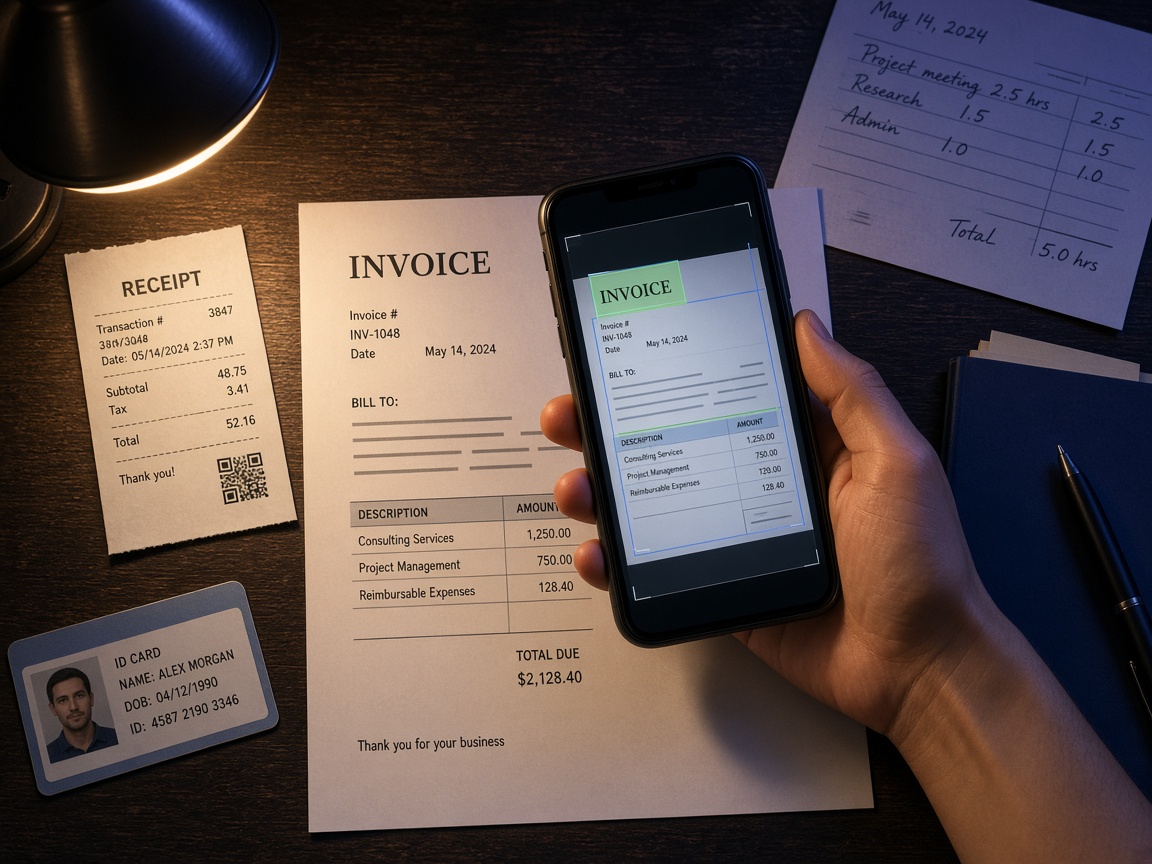
Intelligent Document Processing promises to turn piles of paperwork into structured data. In practice, models often fail on the documents customers actually upload: crumpled receipts, faded stamps, mixed scripts and handwriting. Better training data closes that gap.
Know your document universe
List every document type your model must handle — invoices, receipts, forms, identity documents, business letters — and every language and script. Then think about capture conditions: flatbed scans, phone photos, shadows, skew and low resolution.
The core annotation tasks
- Document classification — what type of document is this?
- OCR transcription — exact text at line, word or character level
- Layout annotation — headers, paragraphs, tables and reading order
- Key-value extraction — invoice number, date, total, name and other fields
- Table structure — rows, columns and cell relationships
Handwriting and multilingual scripts
Handwritten text and Indian scripts are where generic datasets fall short. Native-script annotators are essential to transcribe accurately and to recognise ambiguous characters correctly.
Handle personal data carefully
Identity and financial documents contain sensitive information. Work in access-controlled environments, mask PII where appropriate and keep a clear chain of custody.
Measure quality at the character level
Field-level accuracy matters for extraction, but character-level checks catch the small errors that break downstream automation — a wrong digit in an invoice total, for example.
How Dhvani.ai helps
Dhvani.ai supports handwritten and printed text, forms, receipts, invoices, identity, business and multilingual documents — with document classification and OCR annotation for OCR, Document AI, Intelligent Document Processing and handwriting recognition applications.